Product · Workflows & Connectors
Build AI pipelines visually. Drop into code whenever you like.
Feature builds, model training, scoring and agents on a visual canvas for the whole team, with 54 process types, every major connector and real code where it helps. Then watch every run and promote to production when it is ready.
How it works
From source to production in four steps.
Step 1: Connect
Add a connection once: storage, warehouse, database, feed or API.
Step 2: Design
Drag processes onto the canvas and link them.
Step 3: Run and watch
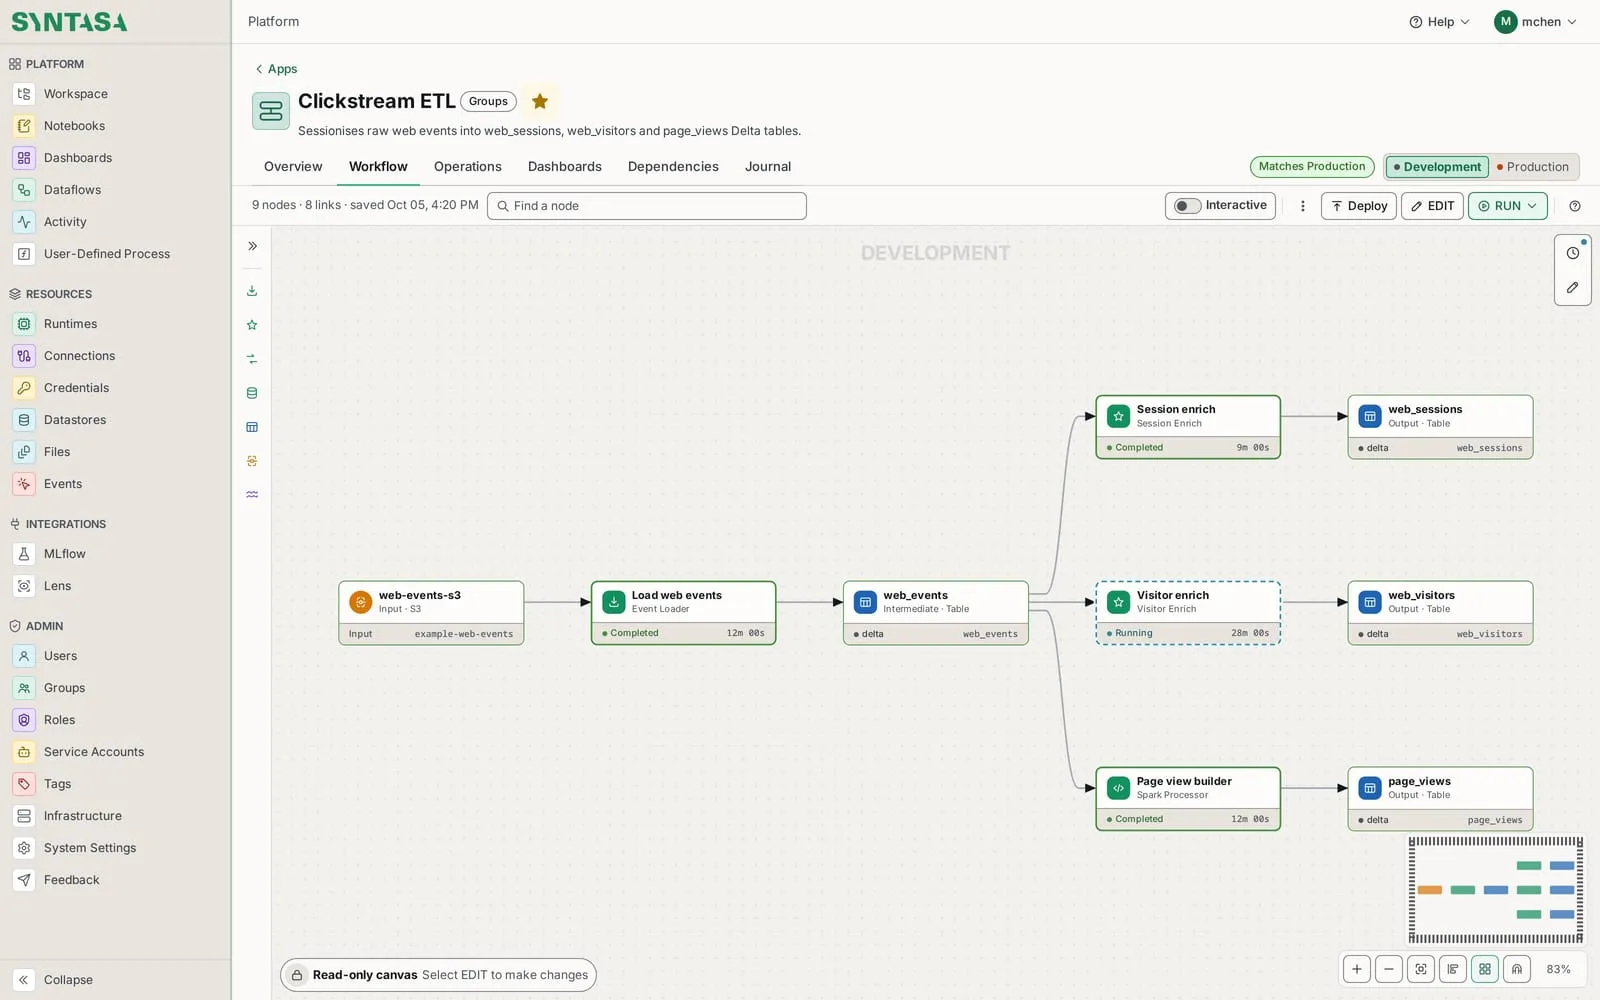
Run it and see each node move through its states.
Step 4: Promote
Move the tested app from development to production.
The canvas
An AI pipeline, end to end.
A custom Spark feature build, a GPU-trained model registered in MLflow, batch scoring and an audience, fed by sessionized web events. Design it, operate it and test each step, all in one app.
Processes
ConnectionEvent StoreID StoreSpark processorSpark MLMLflowPythonDelta outputDashboardAudience Agent+ 44 more
| person_id | sessions_30d | avg_order | churn_risk |
|---|---|---|---|
| p_10482 | 14 | 84.20 | 0.12 |
| p_10517 | 3 | 41.00 | 0.71 |
| p_10533 | 22 | 126.75 | 0.05 |
| p_10561 | 7 | 58.10 | 0.38 |
| p_10602 | 1 | 19.99 | 0.83 |
All runs
Every run in Development. Select a run to see its steps.
- Drag and drop54 process types, from connections to agents.
- Custom Spark codeA Spark processor opens straight into PySpark or Scala.
- Live run statusQueued, running, completed, node by node.
- OperationsEvery run with status, start, duration, runtime and who ran it.
- InteractiveRun one process on a runtime and preview its output.
- Development → ProductionPromote a tested app in a click.
Process library
54 process types for every stage of the work.
Production-ready building blocks to ingest, prepare, model and publish. Your team can also publish its own reusable User-Defined Processes.
Ingest & connect
Bring data in from 20+ connection types, in batch or streaming.
Behavioral data
Event Store and ID Store: raw events into sessions, visitors and identity.
Prepare & enrich
Join, clean, enrich and aggregate with Spark at any scale.
Code steps
SQL, Python, R and Scala, in the same pipeline as visual steps.
Machine learning
Train and score models; notebooks run as scheduled steps.
Containers
Run your own container images as pipeline steps.
Apps & dashboards
Plotly Dash apps and dashboards fed by your outputs.
Open outputs
Delta, Parquet, ORC and Avro tables on your storage.
Reuse and promote
Build once. Share and ship safely.
Every app has a development and a production version, a journal of changes and optional Git. Schedules, dependencies and run history sit alongside, so the next person can pick it up.
- User-Defined Processes package logic your team reuses
- Dev → Prod promotion with a clear match/mismatch indicator
- Journal version history and Git (GitHub, GitLab, Bitbucket)
- Schedules and dependencies between apps
Connectors
Every source, connected once.
Add a connection, keep its secret in the store you already run, and every app can use it. Zero-copy datasets read BigQuery, Snowflake and Redshift in place.
Cloud storage
Warehouses & databases
Analytics & marketing feeds
APIs & files
Git
Secret stores
Behavioral data built in
From raw clicks to people you understand.
Event Store turns raw event streams into sessions and page views. ID Store connects identifiers into visitors and an identity graph you own. Both are ordinary steps on the canvas.
- Raw events
Web, app and feed events
Adobe Analytics feeds and live stream, Matomo, your own trackers.
- Sessions
Sessionized activity
Sessions and page views, ready for analysis.
- Visitors
Visitor tables
Behavior rolled up per visitor over time.
- Identity
Identity graph
Identifiers stitched into one view, in your storage.
Who uses it
One canvas for every role on the data team.
Data engineers
Pipelines with code steps, Git, schedules and dependencies.
Analysts
Visual steps and SQL, without waiting on a ticket.
Data scientists
Notebooks and models as scheduled steps.
Platform owners
Dev/Prod separation, roles and an audit trail.
Bring a pipeline you run today.
We will rebuild part of it on the canvas with you and show how it runs, scales and reports its status.